Skip to content
A scene from Ireland

Neil @ Home

mdadm 1.12.0 released

Well, mdadm 1.12.0 is out now. You can find it at the usual places: http://www.kernel.org/pub/linux/utils/raid/mdadm/ or http://www.cse.unsw.edu.au/~neilb/source/mdadm/.

It seems that whenever I try to type 1.12.0, it comes out as 1.20.0! It happened twice while creating this article, and it happened when I was creating the freshmeat announcement.
I noticed just after I clicked the final 'commit' button. I looked around to see if there was any way to update a pending release, and there wasn't. I guess that makes sense as I had already been asked to check it.

Anyway, the mail went of out to mdadm-subscribers telling them that 1.20.0 was released :-( But when the daily fm-news came out, someone had corrected my blunder to 1.12.0 (I just mistyped it again!). Thankyou to freshmeat!

Now to get stuck into a new release of mdadm 2.0-devel. I want to add a '--hostid' option so that mdadm can determine if a given array was create for "this" host, and can then automatically assemble it safely.
Blog thoughts

No entries for several months... Why? Maybe I just lost the urge.. or maybe there is something more.

I am a person who is keen on structure. Not everything I do it totally structured, but where structure exists I like to find and make use of it. The thing about a blog is it is largely unstructured. It it just a time-ordered series of thoughts. I think that is great, but I would like there to be extra structure as well.

Sometimes different blog entries at different times are connected by a theme. That connection should be made apparent somehow. But this blog doesn't let me.

So I tried creating sub-blogs (look over on the right hand side) but there didn't really get anywhere.

So where next?

Linux md/raid update - UPDATED-1

Further to my md/raid tests reported earlier I retested raid0 throughput on 2.6 as the 'write throughput' numbers I got in the first run were very strange. The second run shows much more reasonable number.

I also tested raid5 with a degraded array (one drive missing). This resulted in slower reads than a fully functional raid5, and same-speed writes.

Why I don't like ACLs and extended attributes

I really don't lile ACL's and extended attributes in filesystems. NFSv4 supports them and it makes it ugly. More and more filesystems are supporting them and it is just added complexity that really is the wrong way to go.

But me just saying that doesn't prove anything. So I should try to convince you, dear reader.

Linux md/raid throughput measurements

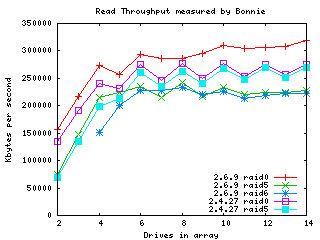
Following some comments on the linux-raid mailing list about poor throughput for raid5 in 2.6, I did some systematic measurement on my test machine to look for patterns. And the result were illuminating.

image

I compared raid0 with raid5 in 2.4.27 and 2.6.9. The results showed that reading from raid5 is significantly slower in 2.6 (as reported) and also that writes were quite a bit slower too, even for raid0 (raid0 reads improved in 2.6). However I didn't get the same degree of slow down that has been reported elsewhere.

UPDATE: more results are available in a subsequent article, showing that the raid0 write through shown here is misleading.

Where Unix went wrong - filesystems - access control

This is one in a (possible) series where I complain about design decisions in Unix. Unix has, on the whole, a very good design, so mistakes stand out rather clearly.

Today's article looks at "Access Control" for files. The "ugo" access control in Unix doesn't seem all that bad until you look at the generalisation known as ACLs - access control lists. Once you see them you have to realise that something was fundamentally wrong to start with.

A final word on AVL trees

One thing bothered me about the AVl code I developed in the preceeding two articles. That is that there were two versions of each of avl_rotate_2 and avl_rotate_3, one for each of insert and delete. I don't like code duplication and the two versions were very similar despite not being identical. This just wouldn't do.

The differences between the rotation routines were two fold. Firstly the rotation went in opposite directions, and secondly the final setting of ->longer was quite different.

The first is easily fixed by passing 1-dir in place of dir for one of the call. The other took a little bit more work, but was achievable by moving some of the setting of ->longer out of the rotate function and into the call site.

The result is a smaller set of code with no significant code duplication. I made a few other minor changes and rearrangements and the result is available, free of charge or any other restrictions, as avl3.c

Non-recursive algorithm for AVL tree deletion

I suggested in my other article on AVL insertion that deletion would probably be fairly symmetric to insertion. It isn't, though there are similarities.

Deletion is somewhat more complicated than insertion, but not greatly so. Like insertion, it can be done neatly without recursion and using constant storage (no stack necessary). The cost of constant storage is that some comparisons need to be done twice (though on average, it is less than one per deletion).

These extra comparisons can be avoided by using one bit of storage for each level of the tree, which is less than twice the base-2 logarithm of the number of elements in the tree. If the tree is stored in memory, then the storage equivalent of two pointers will provide enough bits. This is small enough to be considered constant.

I have found other descriptions of non-recursive AVL deletion elsewhere on the web, specifically at http://benpfaff.org/avl/algorithm.ps and http://www.stanford.edu/~blp/avl/libavl.html/Deleting-from-an-AVL-Tree.html.

I don't find either of these treatments particularly easy to read, but that might be my problem, not theirs. If you don't like what I have written, please try one of those.

Enough introduction - on to the code.

Non-recursive algorithm for AVL tree insertion

I recently wanted to write code for insertion into an AVL tree. Because this code will eventually (hopefully) live inside the Linux kernel, I wanted it to be non-recursive (as recursive code doesn't sit will in the context of the kernel).

I found that taking a non-recursive approach leads to code that is (arguably) cleaner and more transparent than the traditional recursive approach. In fact, I liked what I came up with so much that I thought I would share it.

RAID10 in Linux MD driver

My raid10 module has recently appear in Linus' source tree and should be in the next release of 2.6 - 2.6.9.

I started writing this module about 3 years ago, hit a hiccup, and took 2 and a half year to get back to it. There was a difficulty getting the resync code to work sensibly. As often happens I didn't look for an easy way out that maybe wasn't so complete, but tried to find a completely "right" solution, and ended up with none. "Perfect" was the enemy of "good" once again.

But I finally got back to it earlier this year and got most of it written in a couple of days, most of it working in another couple of days a few weeks later, and the final bugs out about two weeks ago.